The second failure that Lindiwe Mokoena's team investigated at the Blouberg Infrastructure Programme, a fictional public infrastructure programme with about forty construction sites, involved a photograph. A site engineer asked the assistant whether the headwall on the Site 14 culvert had shown any cracking at the last inspection. The assistant said no, describing "a concrete structure in good condition with no visible defects", and attached a photograph as evidence. (The programme's people, systems and figures are illustrative.)
The description was accurate for the photograph. The photograph was the problem. It had been taken at Site 41, forwarded through a messaging app that removed its embedded metadata, and filed in the Site 14 folder by a tired inspector on a Friday afternoon. The inspector's written report for Site 14, which did record hairline cracking, was a scanned PDF whose table of defects had been flattened into a line of text that the retrieval index never matched.
The team's first instinct was to look for a better multimodal model. A better model would have described the wrong photograph more eloquently. What the assistant lacked was not the ability to read images, but an information architecture that knew where the truth about each kind of content actually lives.
Four kinds of content that are not paragraphs
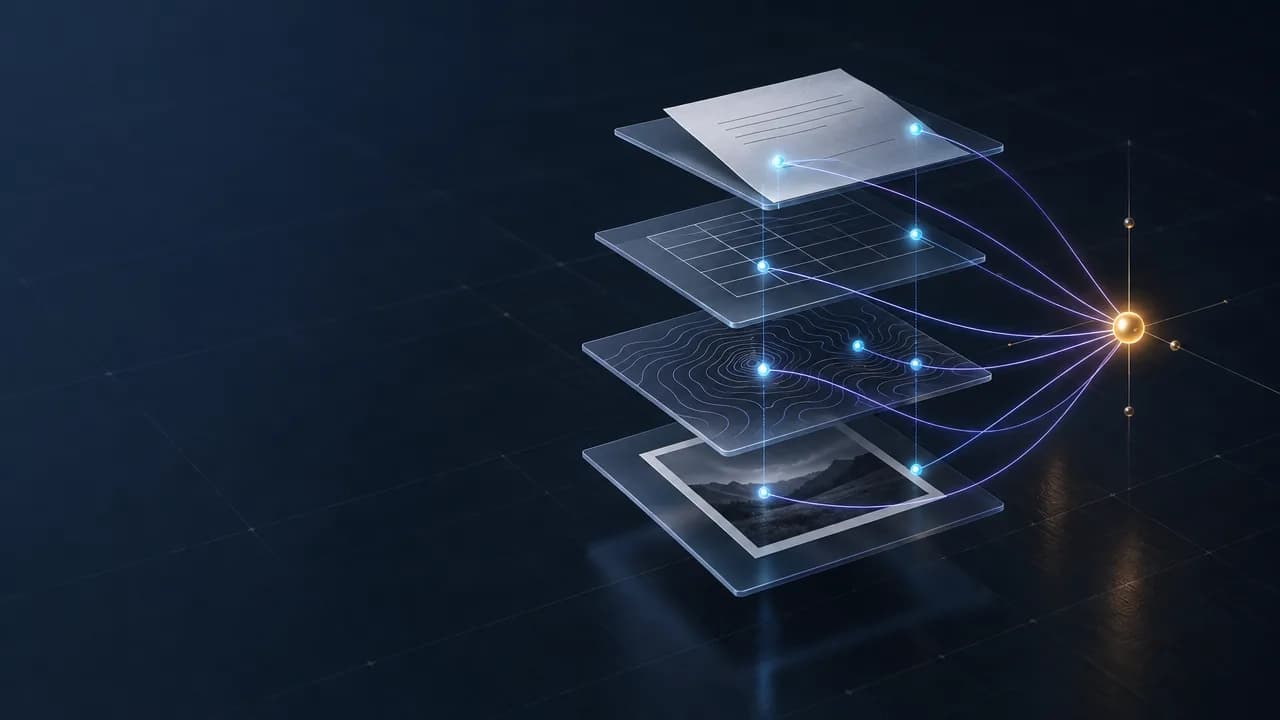
Most retrieval pipelines are designed for prose: split it, embed it, retrieve it. An infrastructure programme's evidence is mostly not prose.
- Tables: bills of quantities, rate schedules, defect registers, payment certificates. The meaning is in the grid: which number sits under which heading, in which row.
- Photographs: site progress and inspection images. The pixels show something, but whether they are evidence depends on where, when and by whom they were taken.
- Drawings: engineering drawings with title blocks, revision letters and notes. A drawing is only meaningful as a particular revision in a drawing register.
- Geographic data: site boundaries, pipeline routes, river crossings. The meaning is in coordinates and spatial relationships, not in words.
Each has what this article calls a native truth: the place where its meaning is authoritative. A multimodal assistant that reads every format as if it were a paragraph, or as if it were only pixels, will miss it.
Route by modality, not by file type
A PDF can contain prose, a table, a scanned photograph and a reduced drawing on consecutive pages. Routing by file extension sends all four through the same pipeline. Blouberg now routes each extracted element by what it is.
| Content | Authoritative representation | What is embedded for search | What is queried exactly | What the answer cites |
|---|---|---|---|---|
| Table | Rows and columns with headers, units and source page | A short description of the table and its row labels | Values, totals, filters on columns | The table, row and page |
| Photograph | The evidence record: site, milestone, time, author, source | The inspector's caption and any reviewed description | Site, milestone, date range | The photograph and its record |
| Drawing | The register entry for a specific revision | Title, notes and register metadata | Drawing number, revision, status | Drawing number and revision |
| Geographic feature | Geometry with a site identifier | Usually nothing | Spatial queries: within, near, intersects | Feature identifier and dataset date |
The table reads across: each kind of content gets a representation that preserves its truth, a small searchable description to help people find it, and exact queries for the parts that must not be approximated.
Tables: keep the grid, then query it
The defect table that went missing at Blouberg was a scanned page. Text extraction had produced a single run of words and numbers with the columns lost, so "hairline crack, headwall, left wing, monitor" had become fragments separated from their row.
The fix had three parts. Tables are now detected and extracted as tables, with their headers, units and source page kept. Each extracted table is checked: row counts match the visible rows, totals add up, and required columns are present. Failures go to a person rather than into the index. Finally, the table's values go into a store that can be queried, while only a short description ("defect register, Site 14, inspection of 12 August") is embedded for search.
This follows the principle in RAG, fine-tuning and knowledge graphs solve different problems: if the answer is a number or a row, query it rather than asking a model to read it off text. The new point for multimodal content is that table extraction is itself a transformation that can fail silently, so it needs its own checks and its own record of which extractor produced which table. Part 5 covers that record.
Photographs: the record around the pixels
A site photograph is evidence only when its context is known. Blouberg now treats each photograph as an evidence record with the image as one field among several.
- Capture metadata. Many cameras and phones embed Exif metadata, defined in a standard maintained by the Camera and Imaging Products Association with JEITA (CIPA DC-008, also published as JEITA CP-3451; Exif 3.1 was published on 30 January 2026, checked on 5 November 2026). It can include capture time and, where enabled, location. It can also be missing, stripped by a sharing app or wrong because a device clock was wrong, so it is a clue, not proof.
- Upload context. Who uploaded the image, from which device and into which inspection.
- Links. The site, milestone and inspection the image belongs to, confirmed by the inspector rather than inferred from the folder.
- Assessment. The inspector's own description and condition rating. This is the authoritative statement of what the photograph shows.
- Generated description. A model-written description can help people search ("headwall", "erosion", "formwork"). It is derived data. It is labelled as generated, stored with the model version that produced it, and never used as the source of a condition statement.
The programme also added two checks when a photograph is filed. If the embedded location is present and falls outside the site boundary, or the capture time falls outside the inspection window, the upload is flagged for the inspector to confirm. The misfiled Site 41 photograph would have been flagged on the first check, had its metadata survived. Because it had not, a third rule was added: any photograph without capture metadata requires the inspector to confirm the site.
Photographs can also contain people, vehicle registrations and private property, which brings personal information into the corpus. The access rules for photographs should be set deliberately, not inherited from a shared folder, as Permission-aware retrieval argues for documents generally.
Drawings: the register is the truth
An engineering drawing without its revision is a liability. Blouberg's pilot had indexed every drawing PDF in the project share, including superseded revisions, and the assistant once answered a question about culvert dimensions from revision B when revision D was current.
The drawing register already existed: a list of drawing numbers, titles, current revisions, status and dates, maintained by the consulting engineers. The fix was to make the register the entry point. A drawing is indexed only as a register entry for a specific revision, its title block and notes are extracted as text, and its status (current, superseded, for information only) travels with it as metadata. Questions about dimensions or details return the drawing number and revision, with a link to the sheet, rather than a model's reading of a reduced image.
Maps: spatial questions need spatial queries
Some questions are geographic: which sites are within two kilometres of a wetland, which pipeline sections cross a particular road, which inspections took place on sites in a given ward. These are spatial queries. Embedding a description of a map does not answer them, and neither does asking a model to read a screenshot.
Blouberg's geographic information system already answered them. The architecture change was to link GIS features to the identifier register from Part 1, so that a spatial query can return site identifiers that the rest of the assistant understands. For organisations that hold spatial data in a knowledge graph, the Open Geospatial Consortium's GeoSPARQL standard (version 1.1 is OGC document 22-047r1) defines an RDF vocabulary and query extensions for geographic data. Blouberg did not need it; its GIS was the authority, and the link through site identifiers was enough.
Failure modes to watch
- Description as evidence. A generated caption is treated as an observation. Keep the human assessment as the authority.
- Silent extraction loss. Tables, scanned pages and handwriting produce empty or scrambled text that is indexed anyway. Count extracted elements against source pages and alert on gaps, as Operating RAG after launch recommends for documents.
- Folder as identity. A file's location is taken to be its site or milestone. Make links explicit and confirmed.
- Superseded visuals. Old drawing revisions and earlier photographs stay retrievable. Index through registers and status, not file shares.
- One pipeline for everything. Every element is chunked and embedded the same way. Route by modality.
A checklist for multimodal content
- Inventory the corpus by content type, not file type: how many tables, photographs, drawings and spatial datasets.
- For each type, name the native truth and the system or register that holds it.
- Extract tables as tables, validate them, and query their values.
- Treat photographs as evidence records with confirmed links; label generated descriptions as derived.
- Index drawings through the drawing register, with revision and status.
- Link geographic features to the same identifiers as the rest of the programme.
- Add evaluation questions for each content type, because a pipeline that passes on prose can fail on tables. Evaluate what was retrieved before what was written describes how to separate the scores.
Key points
- Tables, photographs, drawings and maps carry their meaning in different places. A model that can read images does not change that.
- Route each extracted element by what it is, and give it a representation that preserves its truth.
- Query table values; do not ask a model to read numbers off flattened text.
- A photograph is evidence only with its context. Generated descriptions are derived data, not observations.
- Drawings are authoritative only as register revisions, and spatial questions need spatial queries.
Next: Part 4, Ontologies without the academic fog. All parts are on the series page.
How CloudNala can help
CloudNala reviews multimodal corpora before teams commit to a multimodal model. We inventory your content by type, identify the native truth and owning register for each, test extraction quality on a sample of real tables, scans and photographs, and design the routing, validation and evidence records that let an assistant cite a table row, a drawing revision or a confirmed site photograph rather than a fluent description of the wrong thing.
Work with CloudNala
CloudNala helps organisations move from technology ambition to practical execution across cloud, AI, data, platform engineering and digital services.
Whether you are exploring AI, modernising your cloud environment, building a public-sector digital service, or turning an idea into a working MVP, we can help you shape the roadmap and deliver the next step.
Book a Knowledge Architecture Review or write to us at consult@cloudnala.co.za